XML Sitemap vs Robots.txt: Purpose and Differences
An XML sitemap invites crawlers to your pages; robots.txt tells them where not to go. Learn what each file does and how they work together.
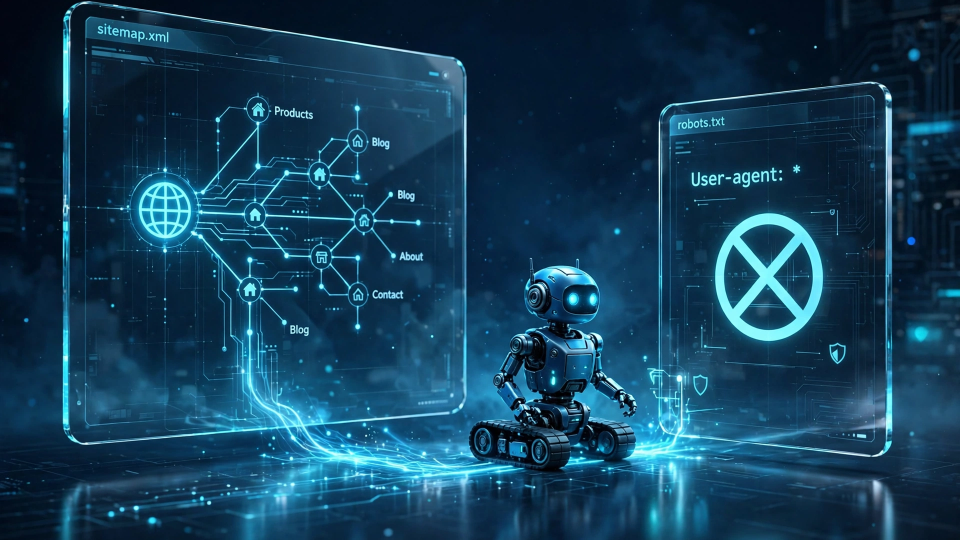
Two small files sit at the root of most websites, and new site owners often confuse them. An XML sitemap tells search engines which pages exist and are worth finding. A robots.txt file tells crawlers which parts of the site they may not fetch. They work on the same visitors — search engine crawlers — but they do opposite jobs, and mixing them up is one of the cheapest ways to hide pages from search results without realising it.
This guide explains what each file does, how the two relate, and what to check after you publish either one. Every example uses the fictional domain example.com.
What each file does
Start with the simplest summary. A sitemap is additive: it points crawlers toward pages. A robots.txt file is subtractive: it keeps crawlers away from paths. Neither file decides whether a page ranks, and neither one can force a search engine to do anything.
Robots.txt: the keep-out list
A robots.txt file is a plain-text file, saved as UTF-8, that lives at exactly one place: the root of a host, at an address like https://example.com/robots.txt. A copy in a subfolder is never read, and each subdomain needs its own file.
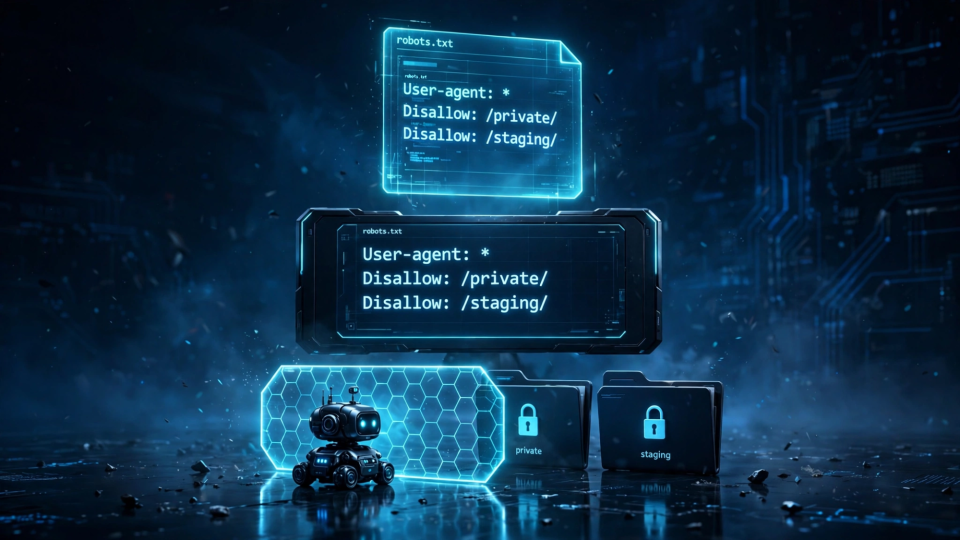
The file is organised into groups. Each group starts with one or more User-agent lines naming the crawler the rules apply to, followed by Allow and Disallow lines. A star (*) means every crawler. A Disallow line lists a URL path prefix: any URL whose path starts with it is off-limits to that group.
Google supports four directives in robots.txt: User-agent, Allow, Disallow, and Sitemap. Two directives that appear in older examples are ignored by Google: Crawl-delay and a Noindex line inside robots.txt. Google also reads at most 500 KiB of a robots.txt file and ignores the rest, so the file should stay short.
The most important fact about robots.txt is what it does not do: it controls crawling, not indexing. A page blocked by Disallow can still appear in search results, usually as a bare URL with no description, if other pages link to it, because Google may index a URL it has never crawled. To keep a page out of results, use a noindex meta tag on the page itself — and do not block the page in robots.txt, since a blocked crawler cannot see the tag.
XML sitemap: the map of pages
An XML sitemap is a structured file, written in XML, that lists the URLs on your site that you consider important. Each page gets a <url> entry with a <loc> address; every other tag is optional. The most useful optional tag is <lastmod>, the date a page was last changed, which helps crawlers prioritise fresh content. The format is defined by the sitemaps.org protocol.
Unlike robots.txt, a sitemap can live anywhere on your site, but crawlers need to find it. You announce it with a Sitemap: line in robots.txt, or by submitting it in Google Search Console. A single sitemap is limited to 50,000 URLs or 50 MB uncompressed; larger sites split their URLs across several sitemaps and list them in a sitemap index file.
A sitemap is a discovery hint, not an instruction. Listing a URL does not guarantee that a crawler will fetch it, and it certainly does not guarantee that the page will be indexed. Pages not listed in a sitemap can still be indexed if crawlers discover them through links. What a sitemap does is make discovery more efficient: it hands crawlers a clean list of the pages you care about, with dates, instead of leaving them to find everything by following links.
The two files side by side
| robots.txt | XML sitemap | |
|---|---|---|
| Purpose | Tell crawlers what to avoid | Tell crawlers what to find |
| Effect | Restricts crawling (subtractive) | Helps discovery (additive) |
| Format | Plain text, UTF-8 | XML (or RSS, Atom, plain text) |
| Location | Exactly one, at the host root (/robots.txt) | Anywhere; announced via robots.txt or Search Console |
| Controls crawling? | Yes, for cooperative crawlers | No — it is an invitation, not a command |
| Controls indexing? | No — a blocked URL can still be indexed | No — listing a URL guarantees neither crawling nor indexing |
| Submit to Google? | No — Google reads it automatically | Yes — via Search Console, or announce it in robots.txt |
How they relate
The two files are not alternatives. A healthy site usually has both: the crawler checks robots.txt first to learn where it may go, then reads the sitemap to learn what exists. Problems start when the two files send contradictory signals.
The Sitemap line inside robots.txt
The most direct link between the files is the Sitemap: directive. It can go anywhere in robots.txt, it applies globally rather than to one user-agent group, and it carries the full address of your sitemap — for example, Sitemap: https://example.com/sitemap.xml.
This one line announces your sitemap to any crawler that reads robots.txt, with no Search Console submission needed. If your sitemap moves, update this line in the same edit; a stale Sitemap: address points crawlers at a file that no longer exists.
When the two files disagree
The classic conflict is a URL that appears in the sitemap but is blocked in robots.txt. The crawler follows robots.txt and does not fetch the page, so the sitemap entry is wasted — and Google Search Console flags the mismatch. Keep the two files consistent: every URL in your sitemap should be crawlable, and nothing blocked in robots.txt should be listed as a page you want found.
The reverse mismatch is subtler. A page that is allowed in robots.txt but missing from the sitemap is not hidden — crawlers can still find it through links — but on a large or new site it may take longer to be discovered. That is the gap a sitemap exists to close.
What neither file can do
Three misconceptions cause most of the damage. First, robots.txt does not remove pages from search results. Blocking a URL stops crawlers from fetching it, but Google can still index the URL from links elsewhere, and blocking it prevents crawlers from seeing the noindex tag that would actually remove it. If a page must leave the index, add noindex to the page and leave it crawlable, or delete the page and let it return a 404 or 410 status. FBSubNet's guide to robots.txt vs noindex works through this distinction in detail.
Second, a sitemap does not guarantee indexing or ranking. It is a hint about which pages exist and when they changed; whether a page is indexed and how it ranks depends on the page itself. Third, neither file is a privacy or security control: a sitemap lists your pages for the world to see, a robots.txt file publicly advertises the folders you blocked, and neither reaches crawlers that ignore the protocol. Sensitive areas need login protection, not a Disallow line.
Worked example: one fictional site, both files
Take a small fictional blog at example.com: a home page, guides under /guides/, tools under /tools/, a member-only area under /private/, and a staging copy under /staging/. Crawlers should find the guides and tools, and stay out of the member area and the staging copy.
First, the sitemap. It lists only the pages meant to be found — the home page, one guide, and the tools page — each with a <lastmod> date. The member area and the staging copy are deliberately absent:
<?xml version="1.0" encoding="UTF-8"?>
<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
  <url>
    <loc>https://example.com/</loc>
    <lastmod>2026-11-10</lastmod>
  </url>
  <url>
    <loc>https://example.com/guides/how-to-write-clear-titles/</loc>
    <lastmod>2026-11-08</lastmod>
  </url>
  <url>
    <loc>https://example.com/tools/</loc>
    <lastmod>2026-11-09</lastmod>
  </url>
</urlset>
Next, the robots.txt file. Writing these rules by hand is easy to get wrong — a missing slash or a typo silently changes what gets blocked — so this one was built with FBSubNet's free Robots.txt Rule Builder instead. The inputs were Disallow paths /private/ and /staging/ (one per line), Allow paths left empty, and Sitemap URL https://example.com/sitemap.xml. Clicking Run tool produced this file, verbatim:
User-agent: *
Disallow: /private/
Disallow: /staging/
Sitemap: https://example.com/sitemap.xml
The tool also showed the message: "robots.txt rules generated. Test on your actual site; robots.txt is not a security or noindex mechanism." Before uploading the file, check each path against your real URLs. The tool runs in your browser and uploads nothing.
Now check the pair against each other. Every URL in the sitemap is allowed by robots.txt, because the only Disallow lines cover /private/ and /staging/, and neither appears in the sitemap. The conflict case is easy to test: if someone added https://example.com/staging/preview.html to the sitemap, a crawler would still refuse to fetch it, because Disallow: /staging/ wins. The fix is to remove the staging URL from the sitemap, not to relax the block.
Checks after publishing
Both files are code, and code needs testing. Work through this checklist after publishing or editing either file, and again whenever the site structure changes.
- Read the live robots.txt. Open
https://yoursite.com/robots.txtin a browser and compare every line against what you intended. Look for typos, missing slashes, and rules copied from staging. A single character is the difference betweenDisallow: /, which blocks the whole site, andDisallow:, which allows everything. - Confirm the sitemap loads. Open the sitemap address from the
Sitemap:line and check it returns valid XML listing your current pages. A sitemap that returns a 404, or lists URLs that now redirect, spends crawler trust. - Test a blocked URL. Pick a URL inside a blocked folder and confirm it is reported as blocked — Google Search Console can report whether a URL is blocked.
- Test an allowed URL. Pick a public page near a blocked pattern and confirm it is allowed. When several rules could match a URL, the most specific — longest matching — rule wins.
- Cross-check the two files. No blocked URL should appear in the sitemap, and no page you want found should be blocked.
- Check the home page and key pages. A broad pattern or a missing slash can block far more than intended. Your most important pages should always come back allowed, with honest
<lastmod>dates in the sitemap. - Re-test after every edit. Neither file warns you when it goes stale. A renamed section, a moved sitemap, or a staging file copied to production can undo the whole setup in one careless upload.
Frequently asked questions
Do I need both files?
Most sites benefit from both, but neither is compulsory. Search engines crawl a site without a sitemap, and a site without a robots.txt file is simply crawled without restrictions. Add a sitemap when links alone might not surface your pages, and add a robots.txt file when you have areas that waste crawl attention, such as admin panels or staging copies.
Can a sitemap override robots.txt?
No. If a URL is disallowed in robots.txt but listed in the sitemap, the crawler follows robots.txt and does not fetch the page. A sitemap announces URLs; it cannot override crawl permission.
Does blocking a page in robots.txt remove it from Google?
No. Blocking stops crawling, not indexing: Google can still index a blocked URL if other pages link to it, usually showing it as a bare URL with no description. To remove a page from results, add a noindex tag to the page itself and leave the page crawlable so Google can see the tag — or delete the page. FBSubNet's guides to robots.txt vs noindex and robots.txt Disallow examples cover the difference and the blocking patterns.
Putting it together
Think of the two files as a map and a set of boundaries for the same visitor. The sitemap says "these pages exist, and these are the ones I care about." Robots.txt says "these paths are off-limits." Get them consistent — every sitemap URL crawlable, every blocked path absent from the sitemap, the Sitemap: line pointing at the file — and both files do a useful job: crawlers find the pages that matter and skip the ones that do not.