Robots.txt Disallow Examples and Common Mistakes
Practical robots.txt Disallow examples for folders, pages, and file types — plus the mistakes that can hide your whole site from search results.
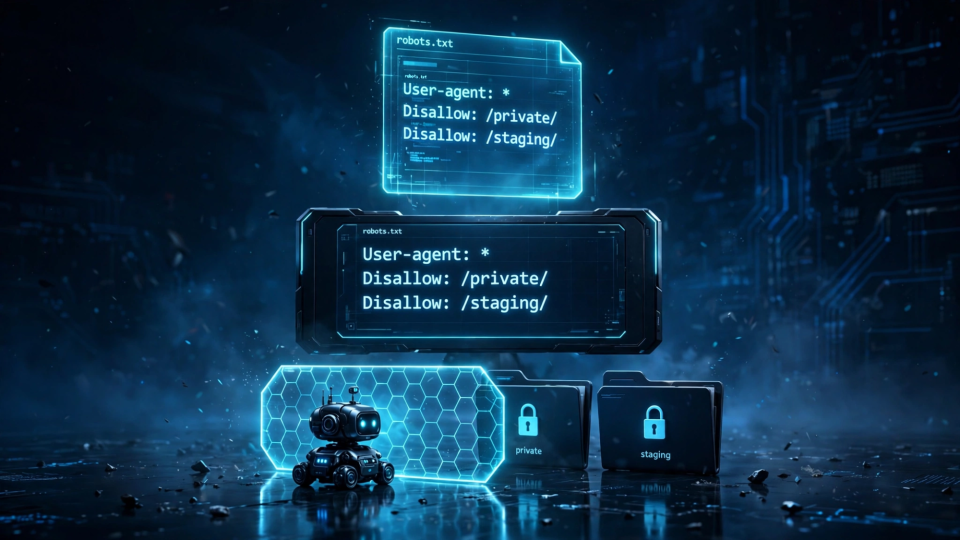
A robots.txt file is a small text file with an outsized job: it tells search engine crawlers which parts of your site they may visit and which parts they should leave alone. The Disallow directive does the blocking, and one careless line can hide far more than you intended — in the worst case, your entire site. This guide covers practical Disallow examples for folders, pages, and file types, a real file built with FBSubNet's free Robots.txt Rule Builder, and the mistakes that catch site owners out.
Most small sites do not strictly need one — search engines crawl a site without it. It becomes useful when you have areas that waste crawl attention: admin panels, staging copies, internal search results, and checkout flows. Used well, Disallow keeps crawlers focused on the pages that matter.
How Disallow Works
A robots.txt file lives at the root of your site — for example.com it is fetched from https://example.com/robots.txt. It must be named exactly robots.txt, saved as UTF-8 text; a copy in a subfolder is ignored. The file is made of groups, each starting with one or more User-agent lines naming the crawler the rules apply to, followed by Allow and Disallow lines. A star (*) as the user-agent means every crawler.
A Disallow line lists a URL path prefix: any URL whose path starts with it is off-limits to that group. So Disallow: /private/ blocks /private/ and everything under it, including /private/settings. Paths are case-sensitive: /Private/ and /private/ are different paths.
Google also supports two pattern characters: an asterisk (*) matches any sequence of characters, so Disallow: /*.pdf$ blocks every URL ending in .pdf, and a dollar sign ($) anchors the match to the end of the URL. When several rules could match the same URL, the most specific — longest matching — rule wins, which is how an Allow line can carve an exception out of a blocked folder. Other crawlers generally follow the same conventions, but behaviour varies, so test important rules.
The most important fact about Disallow is what it does not do: it controls crawling, not indexing. A disallowed page can still appear in search results — usually without a description — if other pages link to it, because Google may index a URL it has never crawled. To keep a page out of results, use a noindex meta tag on the page itself, and do not block the page in robots.txt, since a blocked crawler cannot see the tag. Robots.txt is also not a security mechanism: the file is public, and malicious bots ignore it entirely. Never use it to hide genuinely sensitive content — that needs proper access control.
Google supports four directives: User-agent, Allow, Disallow, and Sitemap. Two directives seen in older examples are ignored by Google: Crawl-delay and a Noindex line inside robots.txt. Google also reads at most 500 KiB of a robots.txt file and ignores the rest, so keep the file short.
Example Directives
Every example below uses the fictional domain example.com; replace the paths with your own. Remember that the file needs a User-agent line before the rules — a Disallow line on its own belongs to no group and does nothing.
Block a whole folder
The most common use is keeping crawlers out of an entire directory, such as an admin area, a private section, or a staging copy:
User-agent: *
Disallow: /admin/
Disallow: /private/
Disallow: /staging/
Each line blocks one folder and everything inside it. Note the trailing slash: Disallow: /private/ blocks the folder's contents, while Disallow: /private without it would also block a page called /private.html, because the match is a prefix match.
Block a single page
To block one page — an expired promotion or a thank-you page — list its exact path, one line per page:
User-agent: *
Disallow: /special-offers.html
Disallow: /thank-you.html
Block a file type
Wildcards let you block an entire file extension without listing every file:
User-agent: *
Disallow: /*.pdf$
Disallow: /*.gif$
The * matches any characters before the extension and $ anchors the match to the end of the URL, so /*.pdf$ blocks /guides/manual.pdf but not /guides/manual.pdf?version=2.
Allow one page inside a blocked folder
Allow punches a hole in a Disallow. Suppose /private/ is blocked but one public help page lives inside it:
User-agent: *
Disallow: /private/
Allow: /private/public-help/
The Allow path is longer and more specific than the Disallow path, so it wins for that one page while the rest of the folder stays blocked. Without it, the help page would be unreachable to crawlers even though it is meant to be public.
Worked example: build the file with the Robots.txt Rule Builder
Writing these rules by hand is easy to get wrong — a missing slash or a typo silently changes what gets blocked. FBSubNet's free Robots.txt Rule Builder generates the file from a form instead. Here is a real run of the tool, with the exact inputs and output.
The brief was a fictional site with two areas to keep out of search results: a /private/ folder for member-only pages and a /staging/ folder holding a test copy. The inputs were Disallow paths /private/ and /staging/ (one per line), Allow paths left empty, and Sitemap URL https://example.com/sitemap.xml. Clicking Run tool produced this file, verbatim:
User-agent: *
Disallow: /private/
Disallow: /staging/

Sitemap: https://example.com/sitemap.xml
The tool also showed the message: "robots.txt rules generated. Test on your actual site; robots.txt is not a security or noindex mechanism." That reminder matters — the generated file is a starting point, not a guarantee. Before uploading it, check each path against your real URLs: a folder you meant to block but typed as /privat/ stays crawlable, and a folder you blocked by mistake stays hidden until you fix the file. The tool runs entirely in your browser and uploads nothing.
Allow everything, and block everything (staging only)
A site with nothing to hide needs only this:
User-agent: *
Disallow:
An empty Disallow means no restrictions; many sites publish exactly this file, plus a Sitemap: line. The opposite — one line blocking every crawler from every page — belongs on staging and test copies only:
User-agent: *
Disallow: /
Publishing Disallow: / on a live site is the classic robots.txt disaster: search engines stop crawling, pages drop out of results, and traffic falls until the line is removed and the site is re-crawled. If you use it on staging, make removing it part of your launch checklist.
Mistakes to Avoid
Most robots.txt damage comes from a handful of repeatable errors.
Using Disallow to remove pages from search results
Disallow stops crawling, not indexing. A blocked page that other sites link to can still show up in results, typically as a bare URL with no description — and blocking it prevents crawlers from seeing the noindex tag that would actually remove it. To remove a page, add noindex to the page and leave it crawlable, or delete the page and let it return a 404 or 410 status.
Blocking your whole site by accident
Disallow: / is one character away from Disallow:, which allows everything. Copying a staging robots.txt to production, or editing the file in a hurry, is how this happens. After any change, fetch your live /robots.txt in a browser and read it.
Blocking the files Google needs to render pages
Google renders pages much like a browser, so it needs your CSS, JavaScript, and images. Old advice suggested blocking script and style folders; current guidance is the opposite — if Google cannot fetch the resources a page needs, it may misunderstand the page or rank it poorly.
Getting the case wrong
Paths in robots.txt are case-sensitive. Disallow: /Admin/ does nothing for /admin/, and Disallow: /images/ does nothing for /Images/. Copy paths from your real URLs rather than typing them from memory.
Putting the file in the wrong place
Robots.txt only works at the root of a host: example.com/robots.txt governs example.com, and a subdomain such as blog.example.com needs its own file. A file named robot.txt or robots.TXT, or one saved inside a folder, is simply never read. The same applies to protocol variants — the file on the https version does not cover the http version, so redirect the variants to one canonical host.
Treating Disallow as privacy or security
Listing a private folder in robots.txt advertises its existence: the file is public, and anyone can read the paths you blocked. Sensitive areas need login protection, not a Disallow line.
Using directives Google ignores, and never testing the file
Crawl-delay and a Noindex line inside robots.txt are both ignored by Google. To slow crawling, use the crawl-rate settings in Google Search Console; to remove a page from the index, use a noindex tag on the page itself. A robots.txt file is also code, and code needs testing: after publishing, check that the live file contains what you intended, then test individual URLs — Google Search Console can report whether a URL is blocked. Test the URLs you blocked, the URLs you meant to allow, and your homepage and key pages, to make sure a broad pattern did not catch them by accident. Re-test after every edit.
How to Check Your Rules After Publishing
Upload the finished file to your site root as robots.txt and confirm it loads at https://yoursite.com/robots.txt. Then work through this checklist:
- Read the live file. Open it in a browser and compare every line against what you intended — look for typos, missing slashes, and rules copied from staging.
- Test a blocked URL. Pick a URL inside a blocked folder and confirm it is reported as blocked in Search Console or by your crawler of choice.
- Test an allowed URL. Pick a public page near a blocked pattern, such as
/private/public-help/, and confirm it is allowed. - Test the homepage and key pages. A broad pattern or a missing slash can block far more than intended. Your most important pages should always come back allowed.
If a test shows a URL blocked that should be allowed, the cause is usually a typo, a missing Allow exception, or a broader pattern catching the URL as a side effect. Narrow the broad pattern first, add the Allow line second, and re-test. Review the file whenever the site structure changes — new sections and renamed folders can make old rules wrong.
Frequently Asked Questions
Does Disallow remove pages from Google?
No. Disallow tells crawlers not to fetch a URL, but Google can still index it if other pages link to it — usually without a description. Use a noindex tag to remove a page, and keep the page crawlable so Google can see the tag.
Can I block AI crawlers with robots.txt?
Yes — add a group naming that crawler, such as GPTBot, with Disallow: / underneath it, leaving your User-agent: * group unchanged. Cooperative crawlers respect the rules; crawlers that ignore robots.txt will ignore the block too.
Putting It Together
Start with what should not be crawled, not with the file itself. List the folders and URL patterns that waste crawl attention or belong only to logged-in users, then write one Disallow line per path and an Allow line for any public page inside a blocked area. Build the file with the Robots.txt Rule Builder to avoid typos, add your sitemap URL, and test the result before and after it goes live. If you are changing URLs as part of a site cleanup, read how to change an existing article URL safely first — a page that is both redirected and blocked is one crawlers cannot follow to its new home. A short, accurate robots.txt file is one of the cheapest SEO wins available: a few lines, checked once, that keep search engines pointed at the pages you actually want found.