How to Remove Duplicate Lines Without Changing Their Order
Learn how to remove duplicate lines from any text list without changing the order, plus the case, whitespace, and ordering pitfalls to watch for.
Why duplicate lines happen
Duplicate lines are rarely anyone's fault. They appear whenever information from more than one place ends up in a single list: a keyword export merged from two SEO tools, an email list combined from two signup forms, server logs repeating the same warning hundreds of times, product SKUs copied from a supplier spreadsheet into a text file, or survey responses pasted together from several sessions. Each source was fine on its own; the merge created the mess.
Cleaning it up sounds trivial until the list grows. Deleting repeats by hand works for twenty lines. At two hundred, your eyes glaze over and you start missing some while accidentally deleting others. At two thousand, manual cleanup is not a plan at all.
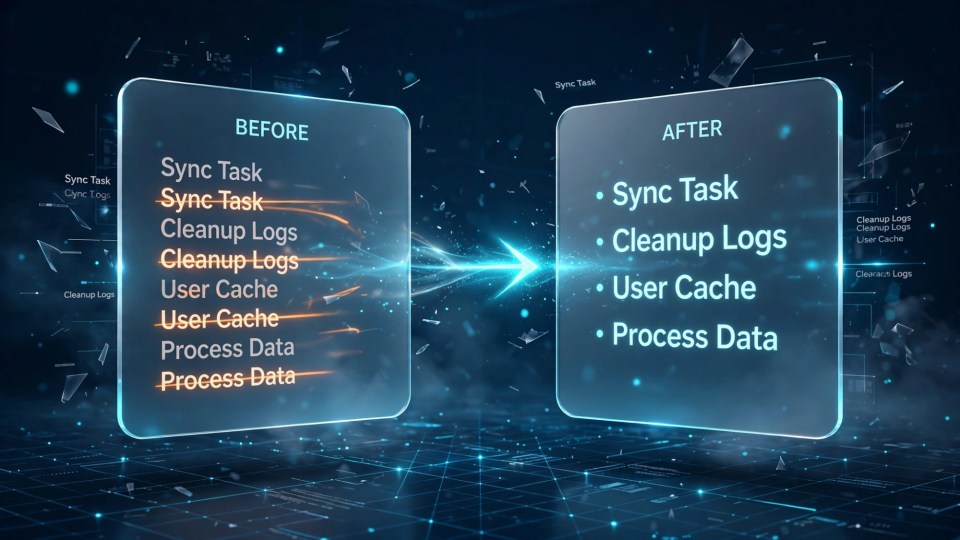
The real requirement is subtler than "remove duplicates." Most lists carry meaning in their order: a keyword list sorted by priority, a task list in the sequence work should happen, a changelog in the order events occurred. A cleanup method that sorts everything alphabetically destroys that information. So the job has two strict requirements: drop every repeated line, and leave everything else exactly where it was. This is called order-preserving deduplication, and it is the standard you should hold every method to.
Remove repeated lines step by step
The fastest reliable method is a browser-based deduplicator. FBSubNet's Duplicate Line Remover runs entirely in your browser — your text is never uploaded to a server, which matters when a list contains email addresses, customer names, or other private data.
- Paste your list into the input box, one item per line. Every line break marks the boundary of one record, so make sure each item really is on its own line before you start.
- Set the matching options. Decide whether the comparison should ignore letter case — treating "Apple" and "apple" as the same line — whether to trim leading and trailing whitespace before comparing, and how to handle empty lines. The right choices depend on your data, and the next sections explain each one.
- Remove the duplicates. Run the tool. It keeps the first occurrence of every unique line and drops every later repeat, without sorting or reordering anything.
- Review the result. Check the count of removed lines against your expectation, skim the cleaned list, then copy it back into your document, spreadsheet, or code.
Here is a concrete example. An 8-line inventory list with repeats goes in:
laptop
headphones
laptop
mouse
headphones
keyboard
mouse
monitor
And this is exactly what comes out:
laptop
headphones
mouse
keyboard
monitor
Eight lines in, five lines out. The first occurrence of each item stays in its original position; only the repeats disappear. Notice that "laptop" keeps its place at the top of the list rather than being moved or merged — that is order preservation doing its job.
Before you paste the result anywhere important, do one sanity check: compare the number of removed lines with what you expected. If the tool reports far more or far fewer removals than you anticipated, one of the matching options is probably set differently than you assumed — most often case sensitivity or whitespace trimming.
Preserve order and review output
Four settings decide what "duplicate" means. Get them right and the result is exactly what you wanted; get them wrong and the tool quietly does something else.
Keep first vs keep last. Nearly every tool keeps the first occurrence and drops later repeats. That is correct for most lists. The exception is data where the newest entry matters most — a price list where later rows carry updated prices, or a log where the final occurrence has the latest status. In those cases you want the last occurrence kept instead. Know which one your data needs before you click.
Case sensitivity. Case-insensitive matching treats "Apple", "apple", and "APPLE" as the same line. That is right for email lists and keyword lists, where capitalization carries no meaning. It is wrong for passwords, code identifiers, and product codes, where case can distinguish genuinely different values.
Whitespace. A trailing space is invisible but real: "keyword " and "keyword" are different lines to an exact comparison. Trimming leading and trailing whitespace before comparing eliminates this whole class of phantom duplicates. Note that trimming only affects the edges — "New York" and "New York" (double space inside) are still different lines.
Empty lines. Decide whether blank lines should be treated as duplicates of each other, removed entirely, or left alone. Blank lines used as section separators should usually be preserved; blank lines that are just formatting noise can go.
Make reviewing the output a habit, not an afterthought. Deduplication compares whole lines exactly, so "seo tool" and "seo tools" are different lines and both survive — a quick skim catches anything the settings missed, and it takes seconds.
Other reliable ways to remove duplicates
The online tool is the fastest option, but it is not the only one. Here is when each alternative earns its place.
Excel and Google Sheets
Select your column, then choose Data > Remove Duplicates. It is quick and familiar, but it edits in place — copy the column to a safe place first if the original matters. In Google Sheets you can also use =UNIQUE(A:A) in a spare column, which produces the deduplicated list without touching the source data at all.
The command line
Two classic commands solve this, with one critical difference:
# Keeps first occurrences, preserves order
awk '!seen[$0]++' list.txt > clean.txt

# Shorter, but SORTS the output
sort -u list.txt > clean.txt
sort -u is the command most people reach for, and it violates the order requirement — fine for unordered data, wrong for everything else. The awk version is the order-preserving choice and worth memorizing.
Python
For files you clean repeatedly, a tiny script beats manual work every time:
lines = open("list.txt", encoding="utf-8").read().splitlines()
seen = set()
clean = []
for raw in lines:
    key = raw.strip().casefold()
    if not key:
        continue
    if key not in seen:
        seen.add(key)
        clean.append(raw.strip())
open("clean.txt", "w", encoding="utf-8").write("\n".join(clean))
This strips whitespace, skips empty lines, compares case-insensitively, and preserves the original order of first occurrences. Adjust the strip() and casefold() calls to match the rules your data needs.
JavaScript
In the browser console or a Node script, a Set preserves insertion order by design:
const clean = [...new Set(text.split("\n").map(l => l.trim()))].filter(Boolean);One line, order-preserving, whitespace-trimmed, empties removed. Ideal for quick ad-hoc cleaning inside web projects.
Case sensitivity, whitespace, and empty lines in detail
These three settings deserve a closer look because they cause nearly every "the tool didn't work" complaint.
Case. Consider a keyword list containing "Laptop buying guide" and "laptop buying guide". With case-sensitive matching they are two different lines and both survive; with case-insensitive matching the second is removed as a repeat of the first. Neither is universally correct — it depends on whether capitalization carries meaning in your data. When in doubt for marketing text, case-insensitive is usually right; for code and identifiers, case-sensitive.
Whitespace. Leading and trailing spaces are the most common invisible culprit, usually introduced by copy-paste. A line reading " Technology" (leading space) looks identical to "Technology" in most editors but compares as different. Trimming before comparison fixes it. Internal spacing — tabs, double spaces, non-breaking spaces — is harder; if duplicates survive trimming, turn on visible-whitespace display in your editor to inspect the actual characters.
Empty lines. A file with ten blank lines scattered through it will, under strict rules, collapse them into one or zero. If blanks separate logical sections, that destroys your formatting. Prefer a "keep blank lines unchanged" option when the tool offers one, or strip blanks in a separate deliberate pass.
Common mistakes to avoid
- Sorting before deduplicating. Sorting makes duplicates adjacent and easy to spot, but it reorders the list. If order matters, never sort as a cleanup step.
- Removing every occurrence of a repeated line. The goal is to keep one copy of each unique line, not to delete lines that appear more than once entirely. If "Orange" appears three times, one "Orange" must remain.
- Case-insensitive matching without checking. Fine for emails and keywords; dangerous for anything where case distinguishes values.
- Ignoring hidden whitespace. When expected duplicates survive, inspect for trailing spaces or tabs before assuming the tool failed.
- Deleting legitimate repeats. Not every repeated line is an error. Server logs, transaction records, and survey responses can contain meaningful repetition — deleting those destroys data. Deduplicate the list, not the dataset's history.
- Working without a backup. Always keep an untouched copy of the original until you have verified the result. Deduplication is easy to redo; reconstructing a destroyed original is not.
Frequently asked questions
Will removing duplicate lines change my list's order?
Not if you use an order-preserving method. Keep-first deduplication leaves every surviving line exactly where it first appeared. Avoid sort -u and any "sort then deduplicate" workflow when order matters.
Should "Apple" and "apple" count as duplicates?
Only when capitalization carries no meaning in your data — email lists, keyword lists, and general text. For code, passwords, and identifiers, keep matching case-sensitive.
Can I remove duplicates without uploading my text anywhere?
Yes. FBSubNet's Duplicate Line Remover processes everything locally in your browser, as do the command-line and script methods above. Nothing leaves your machine.
What if duplicates keep surviving the cleanup?
Check the three usual suspects in order: trailing whitespace, letter-case differences, and invisible characters like tabs or non-breaking spaces. Adjust the matching options and run it again.
Clean lists make everything downstream easier: imports succeed, keyword counts are honest, and logs become readable again. Next time duplicates creep in, run the list through the Duplicate Line Remover and move on.