How to Remove Duplicate Lines Without Changing Their Order
Learn how to remove duplicate lines from text while keeping their original order. Follow simple steps, practical examples, and tips for cleaner lists.
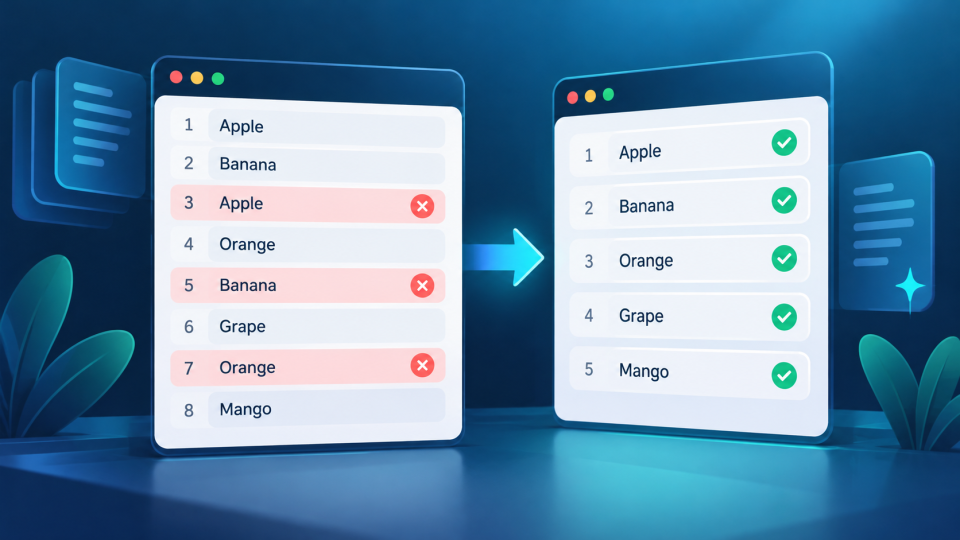
Removing duplicate lines from text without changing their order is simple: keep the first occurrence of each line and remove only the repeated occurrences that appear later. This preserves the original sequence while eliminating unnecessary repetition.
You can do this with an online duplicate line remover, manually in a text editor, or through a short script. The important thing is to avoid sorting the text before removing duplicates.
For example, suppose your list contains:
Apple
Banana
Apple
Orange
Banana
Grape
After removing duplicate lines while preserving their order, the result should be:
Apple
Banana
Orange
Grape
Notice that the remaining items appear in exactly the same sequence as their first appearances.
This guide explains how to remove duplicate lines from text, which settings matter, and how to avoid accidentally changing important information.
What Does Removing Duplicate Lines Without Changing Order Mean?
Duplicate line removal is the process of identifying repeated lines in a text document and removing unnecessary copies.
A line usually means a section of text separated from the next by an actual line break. It could contain a name, website address, keyword, product code, or complete sentence.
When you preserve the original order, you follow two basic rules:
Keep the first occurrence of every unique line.
Remove later occurrences of lines considered identical.
This approach is sometimes called order-preserving deduplication.
It differs from sorting and removing duplicates. Sorting rearranges entries alphabetically or numerically before cleaning them, which may destroy their original sequence.
Why Is Preserving Line Order Important?
The order of a list often carries useful information.
A research list might contain keywords arranged by priority. A task list might reflect the order in which activities should be completed. A collection of product names might follow the sequence in which they were discovered.
Changing that order can make the information less useful.
For example, if your original priorities are:
Fix website errors
Update product pages
Review analytics
Fix website errors
Publish new article
The correct cleaned result is:
Fix website errors
Update product pages
Review analytics
Publish new article
Alphabetical sorting would produce a different arrangement, even though the duplicates were removed.
For this reason, preserving the first occurrence is generally the safest starting point when cleaning ordinary text lists.
How to Remove Duplicate Lines Using an Online Tool
A browser-based duplicate line remover is one of the easiest methods, especially when you do not want to install software or write code.
You can use the FBSubNet Duplicate Line Remover to clean repeated lines while preserving their original order.
The tool provides options for ignoring letter case, comparing lines after removing surrounding spaces, and keeping blank lines unchanged.
Step 1: Copy the Text You Want to Clean
Open the document, spreadsheet, or other source containing your list.
Select the relevant text and copy it.
Ideally, each item should appear on a separate line. If several entries are combined into one line, duplicate line removal will not identify them as separate items.
Step 2: Paste Your Text Into the Tool
Open the duplicate line remover and paste your content into the input field.
Check that the entries appear in the correct sequence before processing them.
For longer lists, it is worth keeping an untouched copy of the original text so you can compare the results afterward.
Step 3: Choose the Appropriate Settings
Decide how the tool should identify duplicates.
The Ignore case option treats differently capitalized versions of the same text as matching entries.
For example, Apple, apple, and APPLE can be treated as duplicates.
The Compare after trimming surrounding spaces option allows lines with extra spaces at the beginning or end to match.
The Keep blank lines unchanged option is useful when empty lines separate sections or improve readability.
Choose these settings according to the type of information you are cleaning.
Step 4: Run the Tool and Review the Result
Click Run tool to process the text.
The tool keeps the first occurrence of each matching line and removes later duplicates without sorting the list.
Review the result to confirm that important entries remain in their expected positions.
You can then use the Copy result button to copy the cleaned text.
According to the tool's description, processing takes place locally in your browser rather than uploading the text to its servers.
Practical Example 1: Cleaning a Repeated Name List
Imagine you are preparing an attendance list for a training workshop.
Several names were entered more than once because registrations were collected from different sources.
Your original text looks like this:
Maya Patel
Jon Carter
Priya Singh
Maya Patel
Kai Ellis
Jon Carter
Olivia Brown
Priya Singh
You want one entry for each person without changing the registration sequence.
After removing duplicate lines, the output becomes:
Maya Patel
Jon Carter
Priya Singh
Kai Ellis
Olivia Brown
The first appearance of every name remains in place.
This is useful when the original sequence represents registration order, submission order, or another meaningful arrangement.
However, remember that identical names do not necessarily represent the same person. When dealing with real records, confirm that duplicate-looking entries genuinely refer to the same individual before deleting them.
Practical Example 2: Removing Duplicate Keywords With Different Capitalization
Suppose you are organizing a list of content topics collected from several research sessions.
Your list contains:
budget laptop reviews
Laptop buying guide
 budget laptop reviews
laptop buying guide
Best laptops for students
budget laptop reviews
There are two types of repetition here.
The phrase budget laptop reviews appears multiple times, including one version with surrounding spaces.
Meanwhile, Laptop buying guide and laptop buying guide differ only in capitalization.
If you enable case-insensitive comparison and trimming of surrounding spaces, the result becomes:
budget laptop reviews
Laptop buying guide
Best laptops for students
The list retains the original capitalization of the first occurrence of each keyword.
This is helpful when combining keyword ideas, article titles, research notes, or other text collected from multiple sources.
It also demonstrates why duplicate detection settings matter. Without the appropriate options, lines that appear similar to a person may not be considered identical.
How to Remove Duplicate Lines Manually
You do not always need a special tool.
For a short list, you can remove repeated entries directly in a text editor.
Start by reading the list from top to bottom. When you encounter a line, check whether the same entry appeared earlier.
If it is the first occurrence, leave it unchanged. If it is a later duplicate, delete that line.
Continue until you reach the end of the document.
When Is Manual Removal Useful?
Manual cleanup works well when you have a small number of entries and need complete control over the result.
It can also be useful when similar-looking lines require human judgment.
For example, Project Alpha and Project Alpha - Final might look related but refer to different versions of a document.
Automatic duplicate removal based on exact matches would correctly keep both. A person reviewing the list can determine whether they actually represent the same information.
However, manually checking hundreds of lines can become tedious and increase the risk of mistakes.
For longer lists, an automated method is generally more practical.
How to Remove Duplicate Lines With Python
If you regularly process text files, Python offers a straightforward way to automate duplicate removal.
The following script reads an input file, keeps the first occurrence of each matching nonblank line, and writes the cleaned text to a separate file.
seen = set()
result = []

with open("input.txt", "r", encoding="utf-8") as file:
    lines = file.readlines()

for line in lines:
    key = line.strip().casefold()

    if not key:
        result.append(line)
    elif key not in seen:
        seen.add(key)
        result.append(line)

with open("cleaned.txt", "w", encoding="utf-8") as file:
    file.writelines(result)
Place your text in a file named input.txt and run the script with Python.
The cleaned content will be saved in cleaned.txt.
How Does This Code Preserve Order?
The script reads lines sequentially.
A set stores comparison values that have already appeared, while a separate list stores the original lines selected for the output.
When the script encounters a new line, it adds that line to the result. When it finds a matching line that appeared earlier, it skips the later copy.
The strip() method removes surrounding whitespace for comparison, while casefold() performs case-insensitive matching.
The script retains the original text of the first matching line rather than replacing its capitalization or spacing.
It also preserves blank lines as separate entries.
If you require exact case-sensitive comparison, replace:
key = line.strip().casefold()with:
key = line.rstrip("\r\n")This removes line-ending characters from the comparison while preserving other characters in the line.
The script is suitable for ordinary text files, but structured data may require a more specialized approach.
Understanding Exact Matches, Spaces, and Capitalization
Before removing duplicates, you should decide what counts as a repeated line.
Different comparison rules can produce different results from the same input.
Exact Matching
Exact matching treats lines as duplicates only when their compared characters are identical.
For example:
New York
new york
New York
With case-sensitive matching, the two versions of New York are considered separate entries, while the final New York is removed.
This is useful for text where capitalization has meaning, such as certain identifiers or code.
Case-Insensitive Matching
Case-insensitive matching ignores differences in uppercase and lowercase letters.
Under this rule, REPORT, Report, and report may be treated as equivalent.
This is useful for general word lists and many content-related tasks, but should be used carefully with case-sensitive identifiers.
Whitespace Matching
Whitespace can create duplicates that are difficult to notice visually.
For example:
Technology
 Technology
Technology
These lines contain different surrounding spaces.
A comparison that trims leading and trailing whitespace can identify all three as matching entries.
However, trimming surrounding spaces does not normally remove differences within a line.
For example, New York and New York contain different amounts of internal spacing and may still be treated as separate values.
Similarly, tabs, unusual whitespace characters, and visually similar Unicode characters can affect matching.
Common Mistakes to Avoid When Removing Duplicate Lines
Sorting the List Before Removing Duplicates
Sorting may simplify visual comparison, but it changes the original sequence.
If preserving order matters, use a method that keeps the first occurrence of each entry without rearranging the text.
Removing Every Occurrence of a Repeated Line
The goal is usually to keep one copy of each unique line, not eliminate every line that appears more than once.
For example, if Orange occurs three times, the first occurrence should remain.
Using Case-Insensitive Matching Without Checking
Sometimes capitalization distinguishes important information.
Two identifiers that differ only by letter case may represent different values.
Only ignore capitalization when those differences are irrelevant to your task.
Ignoring Hidden Whitespace
A line may appear duplicated but still contain an extra space, tab, or invisible character.
If unexpected duplicates remain, inspect the text more closely.
Enable whitespace visibility in your editor when available, or review the comparison settings.
Removing Valid Repeated Records
Not every repeated line is an error.
Server logs, transaction histories, survey responses, and event records may contain legitimate repeated values.
Deleting those records could remove meaningful information.
For structured data, decide whether uniqueness should apply to the entire record or only particular fields.
Useful Tips for Cleaner Results
A few simple habits can make duplicate line removal more reliable.
Keep the original text. Save a backup before making changes, especially when working with important lists or documents.
Decide your comparison rules first. Determine whether capitalization, surrounding spaces, and blank lines should matter.
Test a small sample. Before cleaning a large document, process a few representative lines to see whether the result matches your expectations.
Check the first occurrence. Make sure the intended version of each line remains, particularly when the duplicates have different spelling or formatting.
Review the output. Check the beginning, middle, and end of the cleaned list. If the output is unexpectedly short, your matching rules may be too broad.
For important data, compare the cleaned list against the original rather than assuming that every removed line was unnecessary.
When Should You Avoid Automatic Duplicate Removal?
Automatic duplicate line removal is most appropriate when each line represents an independent item and repeated entries are unwanted.
It may be inappropriate for paragraphs, source code, log files, transcripts, or structured records where repetition has meaning.
For example, two identical lines in a poem may be intentional. Repeated commands in a script may perform necessary operations. Two matching transaction descriptions may correspond to separate purchases.
Removing these lines simply because their text matches could damage the content.
The safest approach is to understand the purpose of the data before applying deduplication.
Frequently Asked Questions
Can I remove duplicate lines without sorting them?
Yes. Use an order-preserving duplicate line remover that keeps the first occurrence of each unique line and deletes later matches. This preserves the original sequence without alphabetical or numerical sorting.
Will removing duplicate lines also remove repeated words?
No. Duplicate line removal compares entire lines rather than individual words within a sentence.
For example, the line Apple Apple Banana remains unchanged unless an identical matching line appears elsewhere. Removing repeated words within a single line requires a different type of text processing.
Can I ignore capitalization while keeping the original text?
Yes. A case-insensitive duplicate remover can compare Apple, apple, and APPLE as equivalent while retaining the spelling and capitalization of the first occurrence.
This is useful for ordinary word lists, keywords, and similar text collections.
Why do some duplicate lines remain after cleaning?
The lines may contain differences that are not immediately visible.
Common causes include surrounding spaces, tabs, internal whitespace, capitalization, and special characters.
Check whether your duplicate remover supports trimming surrounding spaces and ignoring letter case. If the issue continues, inspect the characters in the affected lines.
Conclusion
The easiest way to remove duplicate lines from text without changing their order is to keep the first occurrence of every unique entry and eliminate only later matches.
For quick cleanup, a browser-based duplicate line remover is convenient. For very short lists, manual editing may be enough. If you regularly handle text files, a simple Python script can automate the process.
Whichever method you choose, preserve the original order, select appropriate matching rules, and review the cleaned result. These small precautions help you produce cleaner, more organized text without accidentally losing important information.